
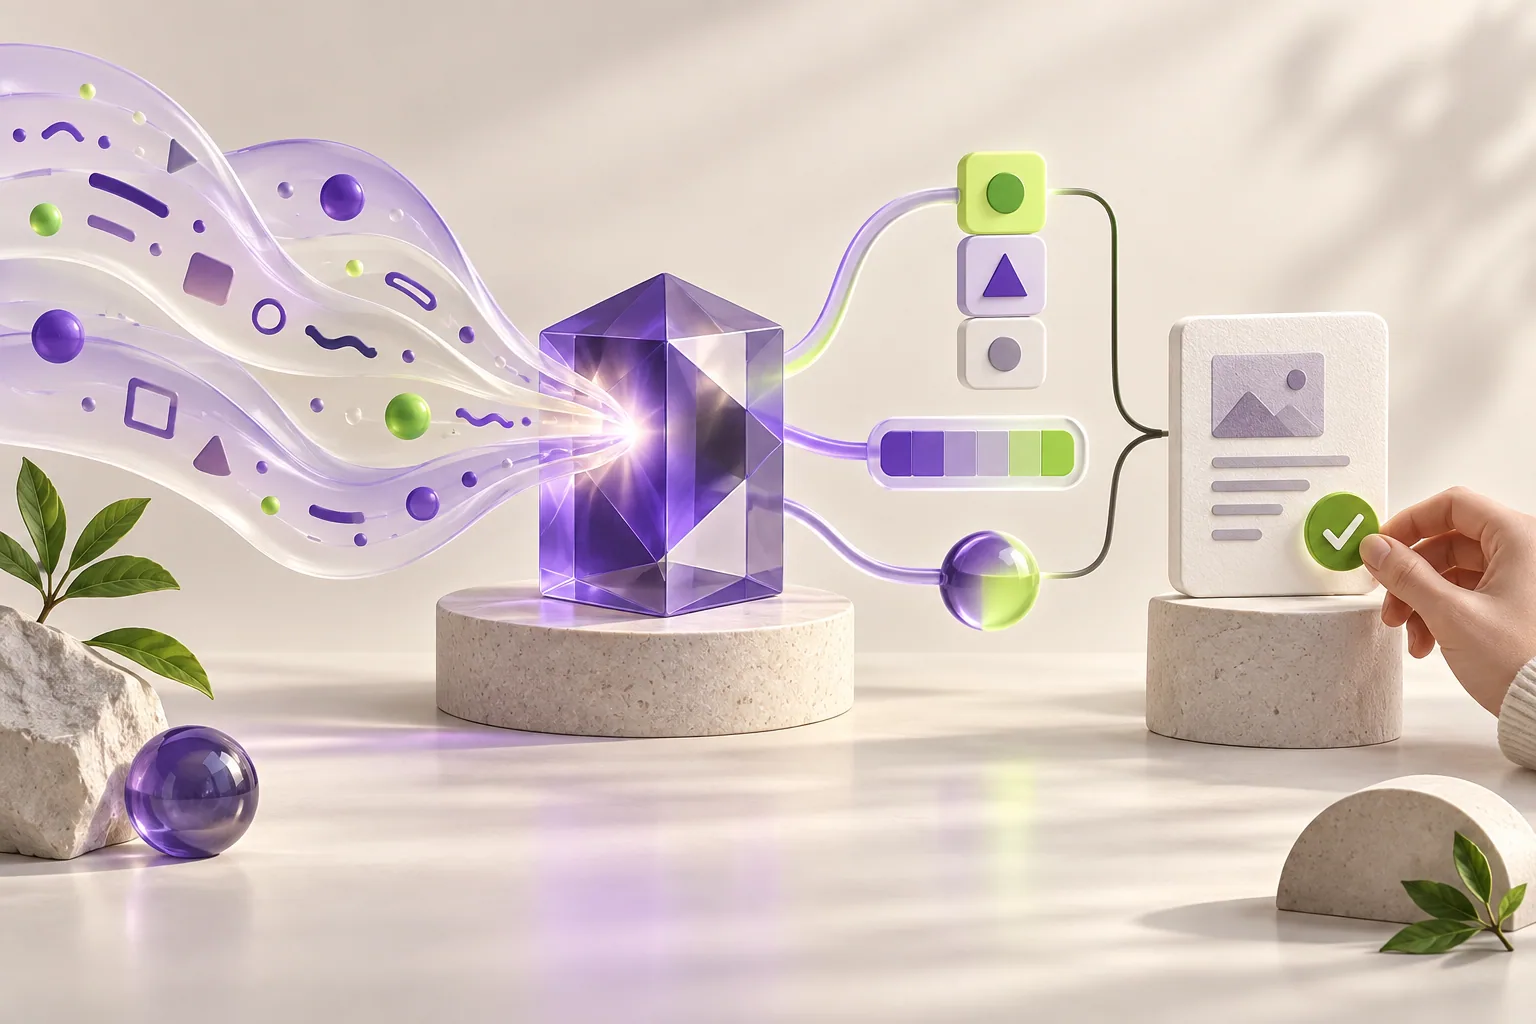
When language understanding becomes an ordinary computing operation, GEO changes too. It is no longer just about writing text with AI. Software can classify sources, brand mentions and content gaps in a targeted way and derive the next sensible step from them. That is exactly the kind of capability we are building into GEO Tool: an autopilot that makes optimization easier and leaves the approval with a human.
We have grown used to treating language models like expensive specialists. We call them in a few places and wait for a detailed answer. This habit shapes our software more than we realize. Often we do not need a paragraph of text at all, but a judgment: relevant or irrelevant, category A or B, review or continue.
Jev by TypeSafe: ask questions, get structured decisions
TypeSafe describes Jev as a “System One” model: a building block for fast, bounded decisions inside software. The input is a state, such as a text with context, plus typed questions. What comes back are values the code can process directly. The TypeSafe introduction explains the principle.
The documentation of the decision primitives distinguishes three types:
- Choice: pick one option from a fixed list, for example the type of a source.
- Score: rate a matter along described levels.
- Noul: answer a yes/no question with a probability between 0 and 1.
Choice and Score also return a confidence value. It can help route uncertain cases to a more thorough review. It does not, however, replace measuring quality on your own use case. A valid data type protects against format errors, not against a wrong judgment.
According to TypeSafe, the questions in a request are evaluated in parallel and independently against the same state. Additional questions should therefore add little to the response time. That is a vendor claim. Whether the advantage holds up in your own system has to be shown by a test that includes the network, retries and failure cases.
Break complex judgments apart, recombine them in code
What interests me most is the design principle behind it. The blanket question “Is this content good?” is hard to verify. Individual questions are far more tangible: Does the paragraph answer the specific customer question? Is there evidence? Does the source fit the topic? Is an important caveat missing?
These judgments can be evaluated separately. Our software decides which of them matter for the next step. If priorities change, we change the weighting or the rule. The actual decision logic stays traceable and testable.
The model does not have to do everything. Regular code reliably checks an HTTP status or an existing schema field. A language judgment pays off where meaning and context matter. And when a later question only becomes possible through an earlier answer, you need another step rather than a supposed independence. The API reference describes the technical format.
What we already do with it in GEO Tool
In GEO Tool we have connected Jev to classify cited sources. This covers, for example, distinguishing between a vendor website, a directory, a community and an independent editorial source. A helpful article on a company blog does not automatically become independent press evidence.
This matters for GEO: ten mentions on your own or controlled profiles mean something different from ten independent reports. A useful analysis has to make these differences visible. When confidence is insufficient, a source stays unclassified; a forced category would only feign accuracy.
We have also implemented an optional shadow evaluation for brand mentions. It assesses mention, position and sentiment in parallel with the existing detection. This comparison does not overwrite its result. It helps us investigate discrepancies before they turn into a change to the regular analysis.
Status as of September 22, 2026: source classification and shadow evaluation are concrete technical building blocks. The applications below describe the direction of our development for the GEO Autopilot; they are not a promise that each of them is already generally available.
An autopilot for GEO: less sorting, better next steps
We are currently building these capabilities further into GEO Tool so that companies can optimize their AI visibility more easily and more precisely. The intended benefit lies in connecting measurement, classification and implementation. Three examples show what we are aligning this development with:
- Detect relevant gaps. Match a customer question against the existing page: is the answer really missing, or is it just hard to find?
- Prioritize actions with reasons. Rate topic relevance, evidence and implementation effort separately. That makes it possible to explain why one text suggestion should be handled before another.
- Check drafts before handover. Verify whether a suggestion fulfills the approved task and whether it contains unsupported claims. Uncertain cases must go back for review.
The workflow behind it stays understandable: measure, propose a suitable action, prepare the approved text for the respective system and measure again after publication. Nothing goes live without approval. Our CMS integrations show which draft paths are available and which are still being tested.
A decision model alone does not improve a ranking in AI answers. It can support the work on suitable actions. Whether a change actually goes hand in hand with more visibility has to be shown by the subsequent measurement. Website readiness, brand mentions and the effect of an action remain different things; more on this in our methodology.
Build ambitiously, measure soberly
When many small language judgments fit into the time budget of a normal interaction, new workflows become interesting. Instead of only checking samples, a system could classify far more events. Instead of coarse categories, several concrete dimensions would be possible. Whether that works economically and reliably, however, is decided by your own dataset.
For a robust trial, I would define four things:
- Reference cases: real examples with human-verified answers, including difficult edge cases.
- Simpler alternatives: rules, caching, embeddings or classic classifiers as a baseline.
- Metrics: wrong decisions, processing time including slow outliers, total cost and the share of unclear cases.
- Stop criteria: decide in advance when the benefit is not enough and which existing workflow takes over.
To explore such possibilities there is also Jevify, an independent community skill for coding agents. It is not an official TypeSafe product. Tools like this can help find suitable places in a codebase and concrete questions to ask. Vendor claims, your own measurements and ideas for new features should be kept clearly separate.
Want to put your GEO on autopilot?
That is exactly what we are working on: less manual sorting, clearer recommendations and a shorter path from finding to approved draft. If you would like to try the development early, join the waitlist for the GEO Autopilot. For a first look at your website, you can already use the free GEO check today.
By Gorden Wuebbe. Adapted for the GEO Tool blog from the LinkedIn post of September 22, 2026 and updated with the current state of development. The technical sources are linked at the respective statements; this article does not contain a comparative performance benchmark of Jev of our own.
Ready for better AI visibility?
Test now for free how well your website is optimized for AI search engines.
Start Free AnalysisRelated GEO Topics
Share Article
Make this blog a preferred source
One click and Google will prioritise articles from geo-tool.com in Top Stories and Discover. The setting applies to your account only and can be undone at any time.
About the Author
 G
- Structured data for AI crawlers
- Include clear facts & statistics
- Formulate quotable snippets
- Integrate FAQ sections
- Demonstrate expertise & authority